When do industrial IoT benchmarking services justify their cost?
Industrial IoT benchmarking services earn their cost when they change a high-consequence decision: whether to qualify a device, scale a connected production line, replace a supplier, invest in edge infrastructure, or defer a costly upgrade. They do not earn it simply by producing a comparison report, a dashboard score, or a broad list of “best practices.”
The economic test is straightforward. A benchmark is justified when the cost of making the wrong decision without independent evidence exceeds the cost of obtaining that evidence. In semiconductor, sensor, power-electronics, and high-reliability manufacturing environments, the wrong decision can create long qualification cycles, intermittent field failures, false maintenance signals, data-quality disputes, production losses, or dependency on a supplier whose capability was assessed too narrowly.
The strongest industrial IoT benchmarking services translate technical variation into a decision that can be defended across engineering, operations, quality, procurement, and finance. That requires more than comparing published specifications. It requires examining how equipment, sensors, networks, data pipelines, and suppliers behave under the actual operating conditions that determine business risk.
Benchmarking is most valuable when published data is insufficient
Industrial systems are commonly purchased on the basis of datasheets, certification claims, sample performance, and supplier demonstrations. Those inputs are necessary, but they rarely settle the questions that matter after deployment.
A temperature sensor may meet its stated accuracy range yet drift when exposed to vibration, contamination, thermal cycling, or an installation geometry different from the test setup. A gateway may support a required protocol but introduce timestamp inconsistency, packet loss, or insecure remote-access practices under production traffic. A predictive-maintenance platform may ingest machine data successfully while delivering alerts too late, too frequently, or without enough context for maintenance teams to act.
These differences are not marginal when connected data is used to control processes, release product, document traceability, optimize energy use, or trigger service interventions. They determine whether an IoT deployment becomes a dependable operational layer or an additional source of ambiguity.
Benchmarking has a clear role where the organization cannot reasonably reproduce the needed comparison internally. This is particularly relevant where:
- multiple device, software, or integration suppliers make performance claims using different test methods;
- the asset base spans legacy controls, modern automation equipment, and several communication protocols;
- sensor readings influence quality, safety, compliance records, or high-value material processing;
- thermal conditions, electromagnetic interference, humidity, vibration, or contamination make laboratory results a poor proxy for plant performance;
- the decision involves high switching costs, lengthy qualification, or multi-site deployment;
- the supply chain requires evidence beyond a supplier’s own quality documentation.
By contrast, a broad external assessment is difficult to justify for a low-cost, non-critical sensing application with stable requirements, a short replacement cycle, and readily comparable products. In those cases, internal acceptance testing and a narrowly defined supplier audit may produce enough evidence at lower cost.
The relevant comparison is not “service fee versus service fee”
Procurement teams often compare benchmarking proposals by day rate, lab fee, number of devices tested, or report length. Those measures matter, but they do not describe the true value of the work. A cheaper service can be more expensive if it tests the wrong variables, applies an irrelevant reference standard, or produces findings that cannot be used in a supplier negotiation or investment decision.
The more useful comparison is between the service fee and the avoidable cost of uncertainty. That uncertainty has several components:
Not every benchmark needs to quantify every outcome in monetary terms. Some risks, such as product liability, process safety, or protection of proprietary manufacturing data, cannot be reduced to a simple savings estimate. But the decision sponsor should still identify the exposure that the work is intended to reduce. If no one can state what decision will change based on the findings, the engagement is likely premature.
High-reliability environments raise the threshold for evidence
The case for independent comparison becomes stronger where hardware performance and data fidelity are tightly linked. Semiconductor production, electronic materials handling, power-device manufacturing, advanced packaging, and industrial sensor applications are examples. Here, an unreliable reading is not merely an IT inconvenience; it can distort process control, maintenance planning, yield analysis, or environmental records.
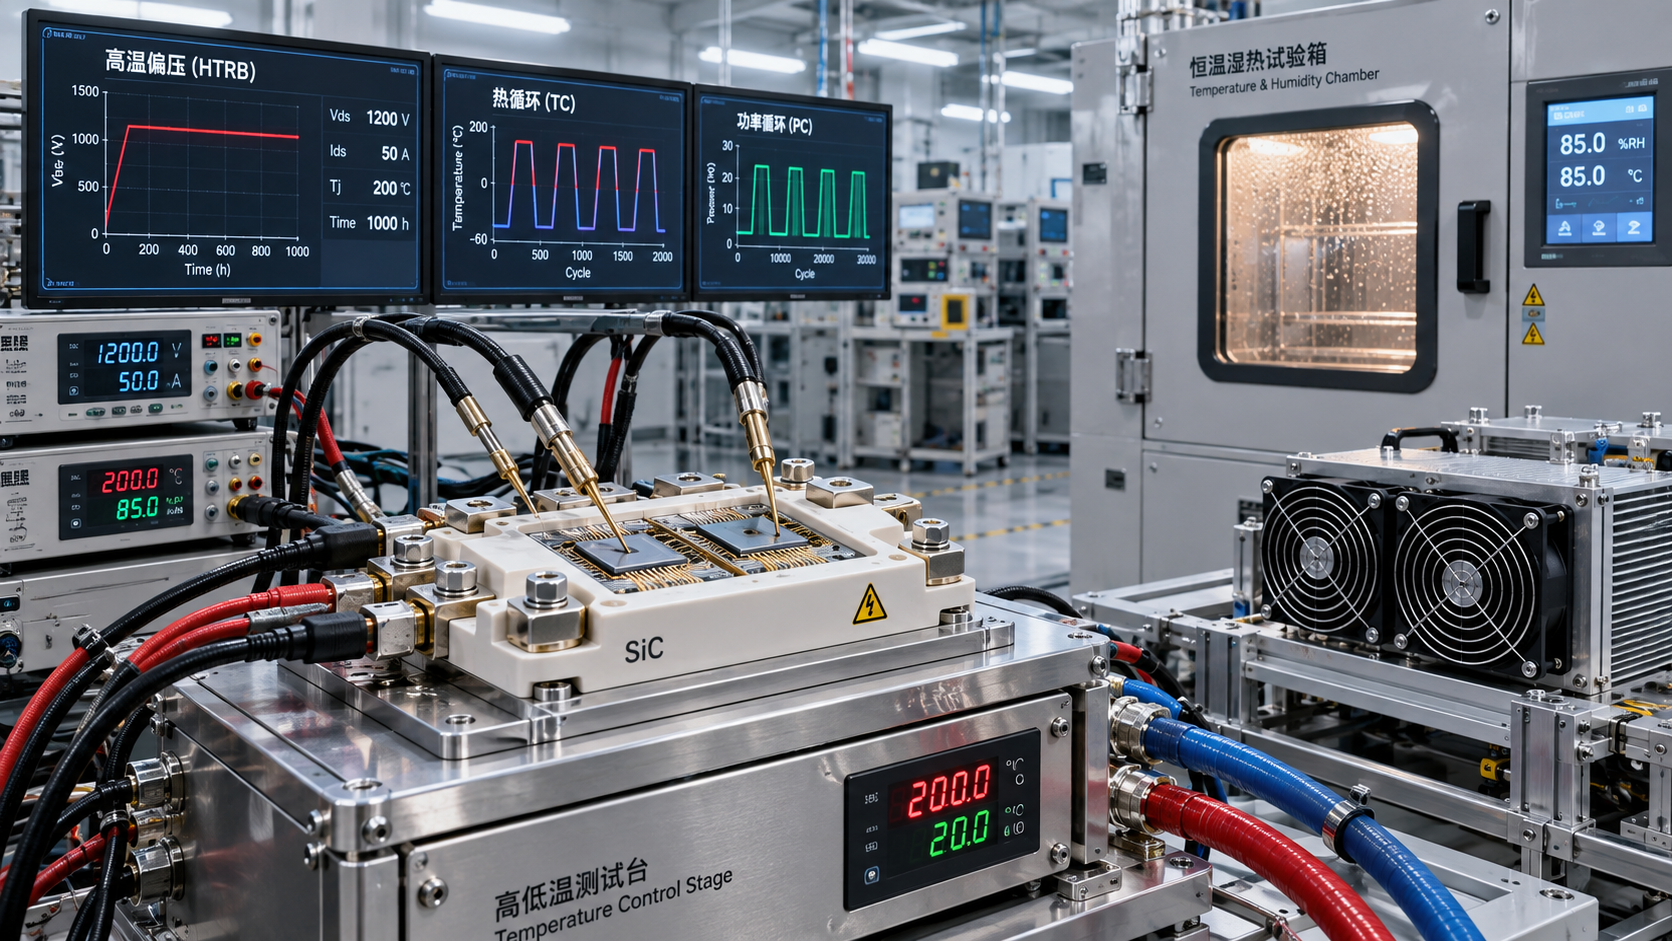
Consider a deployment involving thermal monitoring around power conversion equipment using SiC or GaN devices. A benchmark limited to nominal sensor accuracy says little about whether the measurement chain remains dependable when heat gradients, mounting variation, electromagnetic noise, sampling intervals, and gateway processing are considered together. The practical question is whether the recorded value is sufficiently trustworthy to support a maintenance threshold, derating rule, or process decision.
The same principle applies to condition monitoring in advanced packaging or clean manufacturing environments. Sensor capability must be assessed with the full chain in view: calibration, placement, signal conditioning, protocol conversion, buffering, time synchronization, storage, access controls, and visualization. A good benchmark identifies where a technically acceptable component becomes an operationally weak system.
Standards can provide an important reference point, but they should not be treated as interchangeable labels. SEMI standards may be relevant to particular semiconductor equipment, materials, or manufacturing practices. AEC-Q100 concerns stress-test qualification for integrated circuits used in automotive applications; it is not a general certification for an entire industrial IoT solution. ISO/IEC 17025 addresses the competence of testing and calibration laboratories, not an automatic guarantee that a product will perform in every application. The value of a benchmarking provider lies partly in selecting standards and test methods that match the decision being made rather than assembling an impressive but disconnected list of references.
What separates decision-grade benchmarking from a polished comparison report
A credible service begins with a decision boundary. It defines the asset, process, supplier group, or architecture under review; the operating conditions that matter; the acceptable failure modes; and the evidence required to reach a conclusion. Without that boundary, the work tends to expand into generic maturity scoring that is difficult to act on.
Decision-grade work also makes the test conditions visible. Published benchmark scores have limited value when the reader cannot determine sample selection, firmware version, configuration, load profile, environmental condition, network topology, or data-cleaning method. In industrial IoT, configuration is often inseparable from performance. A comparison between two gateways, for example, is incomplete if one was tested with local buffering enabled and the other was not, or if protocol polling intervals differ.
Independence is equally important. A supplier-funded assessment can provide useful technical information, but it should not be mistaken for a neutral procurement benchmark unless governance, test methods, and data access protect the integrity of the result. The provider should disclose commercial relationships, define how supplier submissions are verified, and distinguish observed performance from supplier-reported capability.
The deliverable should connect evidence to action. A scorecard is useful only if it explains which shortfalls are disqualifying, which can be mitigated through design or process controls, and which deserve commercial protection through warranty terms, service-level commitments, spare-part arrangements, or staged acceptance criteria.
Cost is justified at inflection points, not as a permanent reporting expense
The timing of a benchmarking engagement matters as much as its scope. The most defensible point is before an irreversible commitment: a framework agreement, equipment standardization decision, plant-wide architecture choice, supplier consolidation, or qualification of components that are costly to replace.
Benchmarking can also be justified after a recurring operational problem reveals that internal data is not enough to isolate the cause. Examples include unexplained differences between sites, recurring sensor alarms without confirmed equipment faults, inconsistent quality records, or disputes over whether a device issue originates in hardware, installation, communications, or analytics. In such cases, an outside comparison can create a shared factual basis for corrective action.
It is less effective as a retrospective exercise after a platform has been rolled out and locked into long-term contracts, unless the purpose is to support renegotiation, remediation, or the next procurement cycle. A late benchmark may still expose deficiencies, but its ability to prevent cost is reduced when changing direction requires a major migration.
Scope discipline prevents the benchmark itself from becoming a cost problem
Many industrial IoT programs are broad by design. They may include sensors, PLCs, industrial PCs, wireless networks, edge software, cloud services, cybersecurity controls, maintenance workflows, and enterprise data systems. Benchmarking every layer at once usually produces an expensive assessment with diluted findings.
The scope should follow the decision’s critical path. If the immediate issue is selecting vibration sensors for rotating equipment, the benchmark may need to cover sensing range, noise behavior, mounting sensitivity, calibration traceability, ingress protection, protocol reliability, and integration with the existing historian. It does not automatically need a full review of enterprise cloud architecture.
If the decision is a multi-site data platform, the critical path may instead be identity management, data ownership, interoperability, latency, resilience during network interruptions, exportability, and the practical cost of connecting representative legacy assets. Component-level precision tests alone will not answer that question.
A staged structure often protects value better than a single large engagement. An initial diagnostic can establish whether material variation exists and identify the variables that require deeper testing. A second phase can then focus on finalists, high-risk interfaces, or representative operating conditions. This approach does not mean minimizing evidence; it means buying evidence in the sequence in which it becomes decision-relevant.
Benchmark findings should change commercial terms, not only technical preferences
The outcome of an assessment should influence how the organization buys, not merely which option receives the highest rating. If a supplier performs well under normal conditions but has uncertain behavior under a specific thermal or network condition, the appropriate response may be a controlled pilot, additional acceptance testing, a requirement for configuration documentation, or a contractual obligation to provide firmware support.
Where data fidelity is central, procurement terms may need to address access to raw data, timestamp conventions, metadata retention, audit logs, cybersecurity patch responsibilities, and the right to export data if the platform changes. These issues are easily overlooked when a benchmark focuses only on dashboard features or protocol compatibility.
For devices used in regulated, quality-sensitive, or traceability-dependent environments, the benchmark should clarify calibration and evidence requirements before purchase orders are issued. A device may be technically capable but unsuitable if its calibration documentation, change-control process, or test traceability does not support internal quality procedures. Resolving this after deployment is far more costly than setting the requirement in the qualification stage.
Warning signs that the service is unlikely to pay back
Several proposal patterns should prompt caution. One is a generic maturity model that produces a percentile ranking but does not identify the decision, evidence source, or operating context behind the score. Another is a test plan built entirely around supplier specifications, with no attempt to evaluate installation conditions, interface behavior, or failure modes relevant to the application.
A further concern is a benchmark that promises certainty where the available sample size or test duration can only support directional findings. Short tests can be useful for screening, but they cannot establish long-term reliability, batch consistency, or lifecycle behavior. The report should state those limits plainly.
Cost also becomes hard to justify when the organization has not assigned ownership for acting on the findings. Independent evidence has little value if engineering cannot revise requirements, procurement cannot use the result in negotiations, operations cannot support a pilot, or management has already committed to a vendor regardless of the outcome.
Industrial IoT benchmarking services are therefore not a standard overhead item. They are a targeted form of decision assurance. Their cost is warranted when the assessment addresses a specific, consequential uncertainty; uses transparent and relevant methods; examines the full path from physical signal to operational decision; and produces findings that alter qualification, investment, supplier, or contract choices. When those conditions are absent, a benchmark may still look rigorous while functioning mainly as an expensive report.
Get weekly intelligence in your inbox.
No noise. No sponsored content. Pure intelligence.
 Apr 28, 2026When do rapid prototyping 3D printing services save real costWhen do rapid prototyping 3D printing services save real cost
 Apr 28, 2026What Can Go Wrong in Fan-out Wafer Level Pkg?What Can Go Wrong in Fan-out Wafer Level Pkg?
 Apr 28, 2026What Makes Optical LiDAR Modules Better for Autonomy?What Makes Optical LiDAR Modules Better for Autonomy?
 Apr 28, 20262026 Market Trends in Supply Chain Resilience for Fabs2026 Market Trends in Supply Chain Resilience for Fabs
 Oct 09, 2026How North American semiconductor fabs control airborne molecular contaminationHow North American semiconductor fabs control airborne molecular contamination
 Oct 08, 2026When do custom aluminum extrusions reduce fabrication costs?When do custom aluminum extrusions reduce fabrication costs?
 Oct 07, 2026How semiconductor packaging affects thermal reliability in EV power electronicsHow semiconductor packaging affects thermal reliability in EV power electronics
 Oct 06, 2026When do corrugated plastic boxes make sense for returnable shipping?When do corrugated plastic boxes make sense for returnable shipping?
 Oct 05, 2026What to verify before choosing semiconductor distributors in North AmericaWhat to verify before choosing semiconductor distributors in North America
 Oct 04, 2026How to assess a high purity materials manufacturer’s traceabilityHow to assess a high purity materials manufacturer’s traceability
 Oct 03, 2026How SiC power conversion solutions improve high-voltage invertersHow SiC power conversion solutions improve high-voltage inverters
 Oct 02, 2026When do SiC MOSFET benefits justify the higher device cost?When do SiC MOSFET benefits justify the higher device cost?
 Oct 01, 2026Which semiconductor reliability testing standards apply to power devices?Which semiconductor reliability testing standards apply to power devices?
 Sep 30, 2026How to qualify a semiconductor photoresist supplier for KrF/ArF productionHow to qualify a semiconductor photoresist supplier for KrF/ArF production
 Sep 29, 2026What image quality should portable ultrasound scanners deliver for triage?What image quality should portable ultrasound scanners deliver for triage?
 Sep 28, 2026How sub-ppb impurity control gases protect process consistencyHow sub-ppb impurity control gases protect process consistency
 Sep 27, 2026How chemical purity affects defect rates in semiconductor depositionHow chemical purity affects defect rates in semiconductor deposition
 Sep 26, 2026When do high voltage power semiconductor devices need SiC over IGBTs?When do high voltage power semiconductor devices need SiC over IGBTs?
 Sep 25, 2026How to verify quality controls at a die casting parts supplier in ChinaHow to verify quality controls at a die casting parts supplier in China
 Sep 24, 2026How to verify electronic gas purity for sub-ppb semiconductor processesHow to verify electronic gas purity for sub-ppb semiconductor processes
 Sep 23, 2026When sensory data integration improves industrial motion monitoringWhen sensory data integration improves industrial motion monitoring
 Sep 22, 2026How supply chain resilience reduces the cost of production disruptionsHow supply chain resilience reduces the cost of production disruptions
 Sep 21, 2026What autonomous systems OEMs should verify before sourcing LiDAR modulesWhat autonomous systems OEMs should verify before sourcing LiDAR modules
 Sep 20, 2026How gas purity affects defect density in epitaxial wafer growthHow gas purity affects defect density in epitaxial wafer growth
 Sep 19, 2026How substrate defects affect third-generation material device yieldHow substrate defects affect third-generation material device yield
 Sep 18, 2026How trace impurities in specialty process gases affect wafer yieldHow trace impurities in specialty process gases affect wafer yield
 Sep 17, 2026How European REACH rules affect specialty electronic chemical sourcingHow European REACH rules affect specialty electronic chemical sourcing